Introduction
The MAP rule compares posteriors. For a vector these involve products and divisions that are slow to compute. A discriminant function is a simpler score for each class that puts the classes in the same order as the posterior. It gives the same decision with less work, and it turns the decision into classification: compute one score per class and pick the largest.
Main idea
$g_i(\mathbf{x})=\ln p(\mathbf{x}|\omega_i)+\ln p(\omega_i)$. Decide the class with the largest $g_i(\mathbf{x})$. The boundary between class $i$ and class $j$ is $g_i(\mathbf{x})=g_j(\mathbf{x})$. A score is not a probability: only the order of the scores matters.
Overview
Each arrow keeps the order of the classes, so the largest is the largest posterior.
Step 1: changes that keep the decision
You can change every class's score in any of these ways, and the class with the largest value stays the same:
- add or remove a term that is the same for every class
- apply an increasing function, such as , to every score
- multiply every score by the same positive number
Changes that are not allowed:
- removing a term that differs between classes
- multiplying by a negative number, which flips the order
Step 2: derivation
The Bayesian (optimal) classification maximizes the posterior, and so minimizes the classification error:
Apply the allowed changes one at a time:
- write the posterior with Bayes formula,
- is not a function of , so drop it to get
- take the natural logarithm, which is increasing, so the order does not change
The Bayesian classification is then: evaluate for every class, and find the class with the maximum value for the given pattern .
Why take the natural logarithm:
- is a monotonically increasing function, so it does not affect the decision result
- it turns the product into a sum
- it simplifies the evaluation when is an exponential function, such as a Gaussian, because cancels the
flowchart LR
    X["Pattern x"] --> G1["g1(x)"]
    X --> G2["g2(x)"]
    X --> Gc["gc(x)"]
    G1 --> M["Select the<br/>maximum"]
    G2 --> M
    Gc --> M
    M --> D["Decide ωk"]
Step 3: decision boundary and regions
The decision changes where the top two scores tie, so the boundary between class and class is the set of points where these two are the top scores and:
With three or more classes, can also hold where both lose to a third class, and those points are not on the boundary. The decision region is the set of all where is the largest score.
For two classes, one function is enough:
Decide if and if . The boundary is .
Why do we need this
It turns "compare posteriors" into "compute a score and pick the biggest", which is how classifiers are built and run. It also gives a clear recipe for the boundary: set two scores equal and solve.
Next step
To compute we need a formula for . Gaussian Discriminant Function uses the multivariate Gaussian.
Visual 1: log keeps the winner
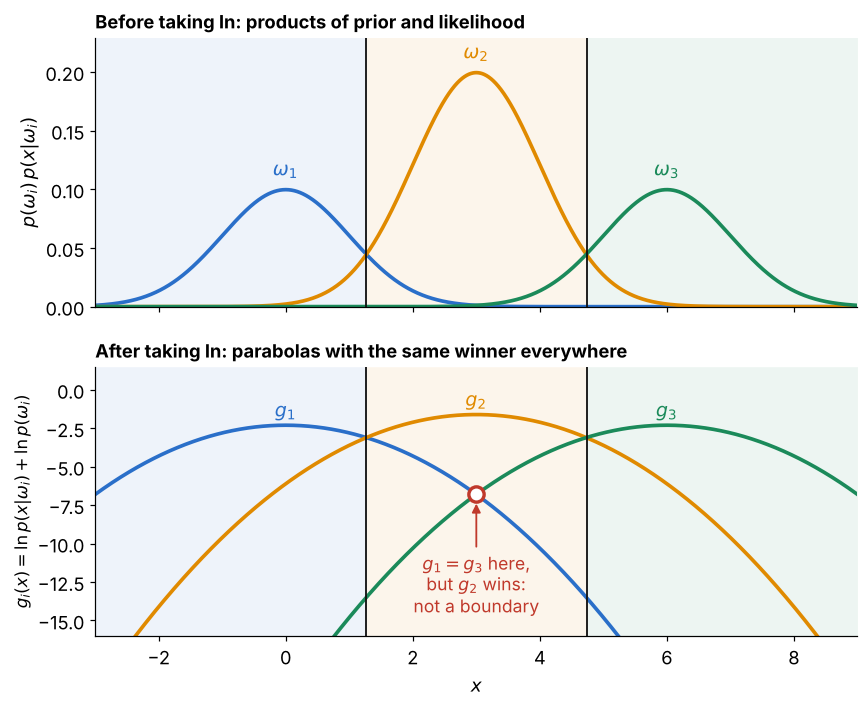
Three 1D Gaussian classes with priors , , :
- top: the products , with each shaded band showing which class is largest
- bottom: the scores after taking ; the curves become parabolas, but the bands and the black boundaries stay exactly where they were
- the red circle is a point where , but is larger there, so it is not on any boundary, as Step 3 warns
Visual 2: one function for two classes
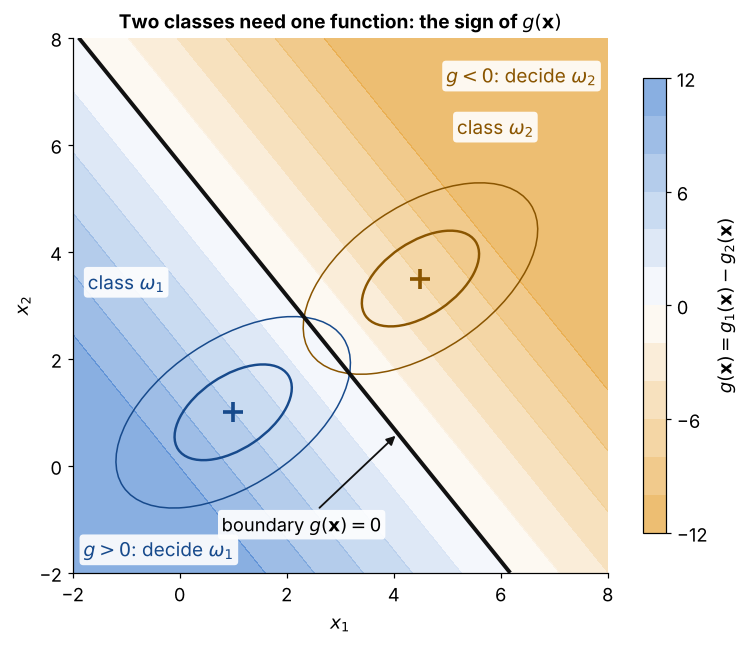
Two classes with the same shape, drawn as their contour ellipses:
- the colour is the value of , blue where (decide ) and orange where (decide )
- the black line is , the boundary, so one sign test replaces comparing two scores
- , so the darker the colour, the more one class beats the other
- both classes have the same shape here, which makes the boundary straight; with different shapes it would curve