Overview
- a ViT cuts an image into 16 by 16 patches and treats each patch like a word token
- this lets the same Transformer that reads text also read images
- steps: patches, patch embeddings with a [CLS] token, position embeddings, Transformer encoder, classification head
- main contrast with CNNs: global attention from the first layer, so it looks at shape more than texture
Vision Transformers (ViT) apply the Transformer architecture that is originally designed for text directly to images. Instead of treating an image as a grid of pixels processed by convolutions, ViT splits the image into a sequence of fixed-size patches and treats each patch like a word token.
CNN vs. ViT at a Glance
| CNN | ViT | |
|---|---|---|
| Receptive field | Local: filters see small neighbourhoods | Global: attention sees every patch at once |
| Inductive bias | Built-in (translation equivariance, locality) | Minimal: learns structure from data |
| What it focuses on | Textures and local features | Shapes and global structure |
| Data efficiency | Better with less data | Needs large datasets to shine |
How It Works (patch size = 16×16)
1. Patch Extraction
The input image is divided into a grid of non-overlapping 16×16 patches:
- An 8×8 grid → 64 patches total
- Each patch contains RGB values across 3 channels
- Values are normalised, then each patch is flattened into a 1D vector:
16 × 16 × 3 = 768values
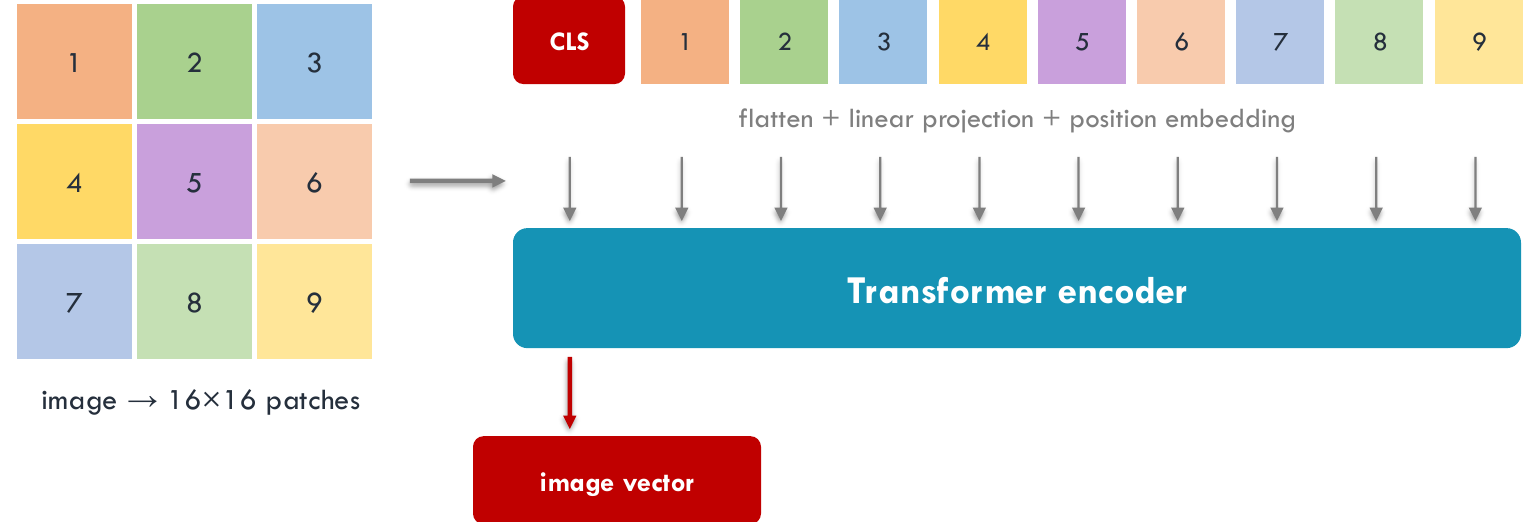
The token count follows from the image size. A 224×224 image with 16×16 patches gives a 14×14 grid, which is 196 tokens. So ViT treats an image as a sequence of "visual words" and uses the same Transformer as text. This unifies vision and language processing, which is why ViT is the backbone of CLIP, MAE, DINO and most multimodal LLMs.
2. Patch Embeddings
Each flattened patch is projected into an embedding vector via a learned linear layer which is analogous to word embeddings in NLP:
Patch (768,) → Linear layer → Embedding (D,)
An extra learnable [CLS] token is prepended to the sequence. Its final representation is used for classification.
3. Positional Embeddings
Since Transformers have no built-in notion of order, positional embeddings are added to each patch embedding so the model knows which patch came from where in the image:
Final input = Patch Embedding + Positional Embedding
4. Transformer Encoder (Attention)
The sequence of embeddings passes through multiple Transformer encoder blocks, each containing:
- Multi-head self-attention: every patch attends to every other patch, capturing global relationships
- MLP / FFN: applied per patch independently
This is where ViT gets its Global Receptive Field: every patch can directly influence every other patch, regardless of spatial distance.
5. Classification Head
After all encoder blocks:
- The [CLS] token embedding (updated by attending to all patches) is extracted
- It passes through an MLP with softmax to produce class probabilities
[CLS] embedding → MLP → Softmax → class probabilities
Why the Global Receptive Field Matters
CNNs classify images based on textures (local patterns), which can sometimes lead to incorrect predictions if a texture is present in the wrong context. ViT, by attending globally from the very first layer, tends to focus on object shape which is generally a more robust feature for recognition.