Definition
- Part-of-speech is the process of reading a sentence and automatically labelling each word with its corresponding grammatical role based on its context
Purpose & Function
- POS allows us to understand structure and semantic context of words in speech
- POS tagging allows computers to contextualise these words for a more accurate processing and comprehension
- Previously we did this for entities, but now under POS tagging, we are doing it for all tokens
Tagging Methods
- using linguistic patterns, context and predefined dictionaries
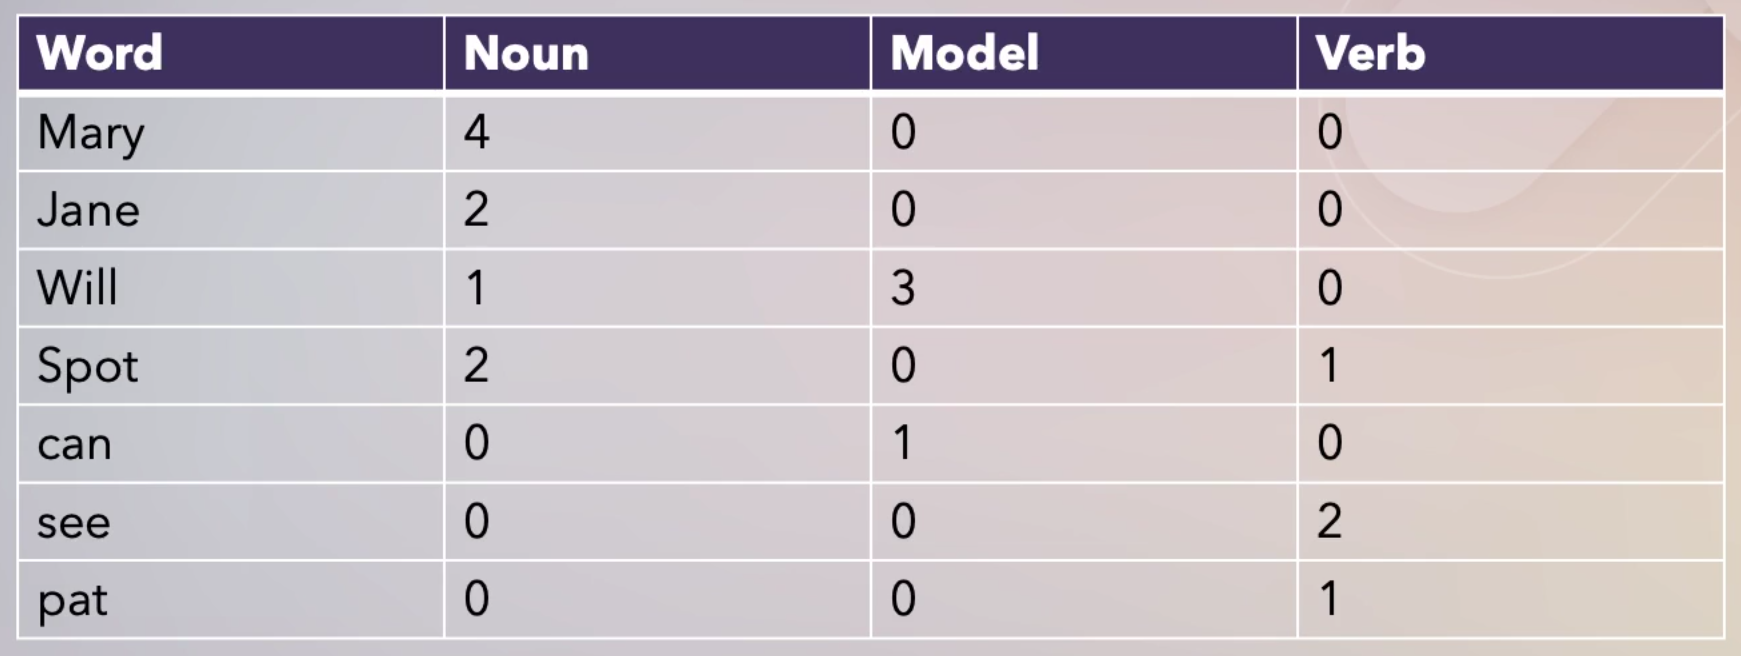
- probability models, such as Hidden Markov Models
# Load spacy's smal english model, define our sentence, run sentence thru model
nlp = spacy.load("en_core_web_sm")
sentence = "This course is lectured by Dr. S. Supraja, and Simon Liu at NTU, Singapore."

doc = nlp(sentence)

# Process the text for coarse-grained POS tagging
for token in doc:
	print(f"{token.text}[{token.pos_}]")
This[DET]
course[NOUN]
is[AUX]
lectured[VERB]
by[ADP]
Dr.[PROPN]
S.[PROPN]
Supraja[PROPN]
,[PUNCT]
and[CCONJ]
Simon[PROPN]
Liu[PROPN]
at[ADP]
NTU[PROPN]
,[PUNCT]
Singapore[PROPN]
.[PUNCT]
# Process the text for fine-grained POS tagging
for token in doc:
    print(f"{token.text}[{token.tag_}]")
This[DT]
course[NN]
is[VBZ]
lectured[VBN]
by[IN]
Dr.[NNP]
S.[NNP]
Supraja[NNP]
,[,]
and[CC]
Simon[NNP]
Liu[NNP]
at[IN]
NTU[NNP]
,[,]
Singapore[NNP]
.[.]
token.pos_gives course-grained tag- it comes from Universal POS tagset (UPOS) that contains a small, language-independent set of about 17 broad categories
token.tag_gives fine-grained tag- it come from detailed, language-specific tagset (Penn Treebank tagset) with 40+ tags that encode morphological detail like tense, number, and degree
nlp.pipe() is used to process text in batches rather than one by one which improves the efficiency of text processing.
from nltk import Tree

def tok_format(tok, coarse=False):
	if coarse:
		return "[".join([tok.orth_, tok.pos_]) + "]"
	return "[".join([tok.orth_, tok.tag_]) + "]"

def to_nltk_tree(node, coarse=False):
	if node.n_lefts + node.n_rights > 0:
		return Tree(tok_format(node), [to_nltk_tree(child, coarse=coarse) for child in node.children])
	else:
		return tok_format(node, coarse=coarse)

[to_nltk_tree(sent.root, coarse=True).pretty_print() for sent in doc.sents];
[to_nltk_tree(sent.root).pretty_print() for sent in doc.sents];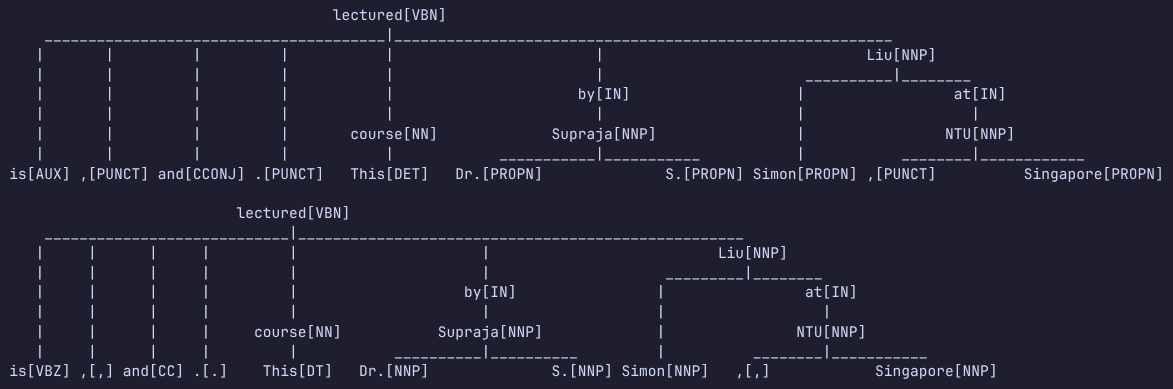
Process
- Tokenize
- then POS tag them
Applications
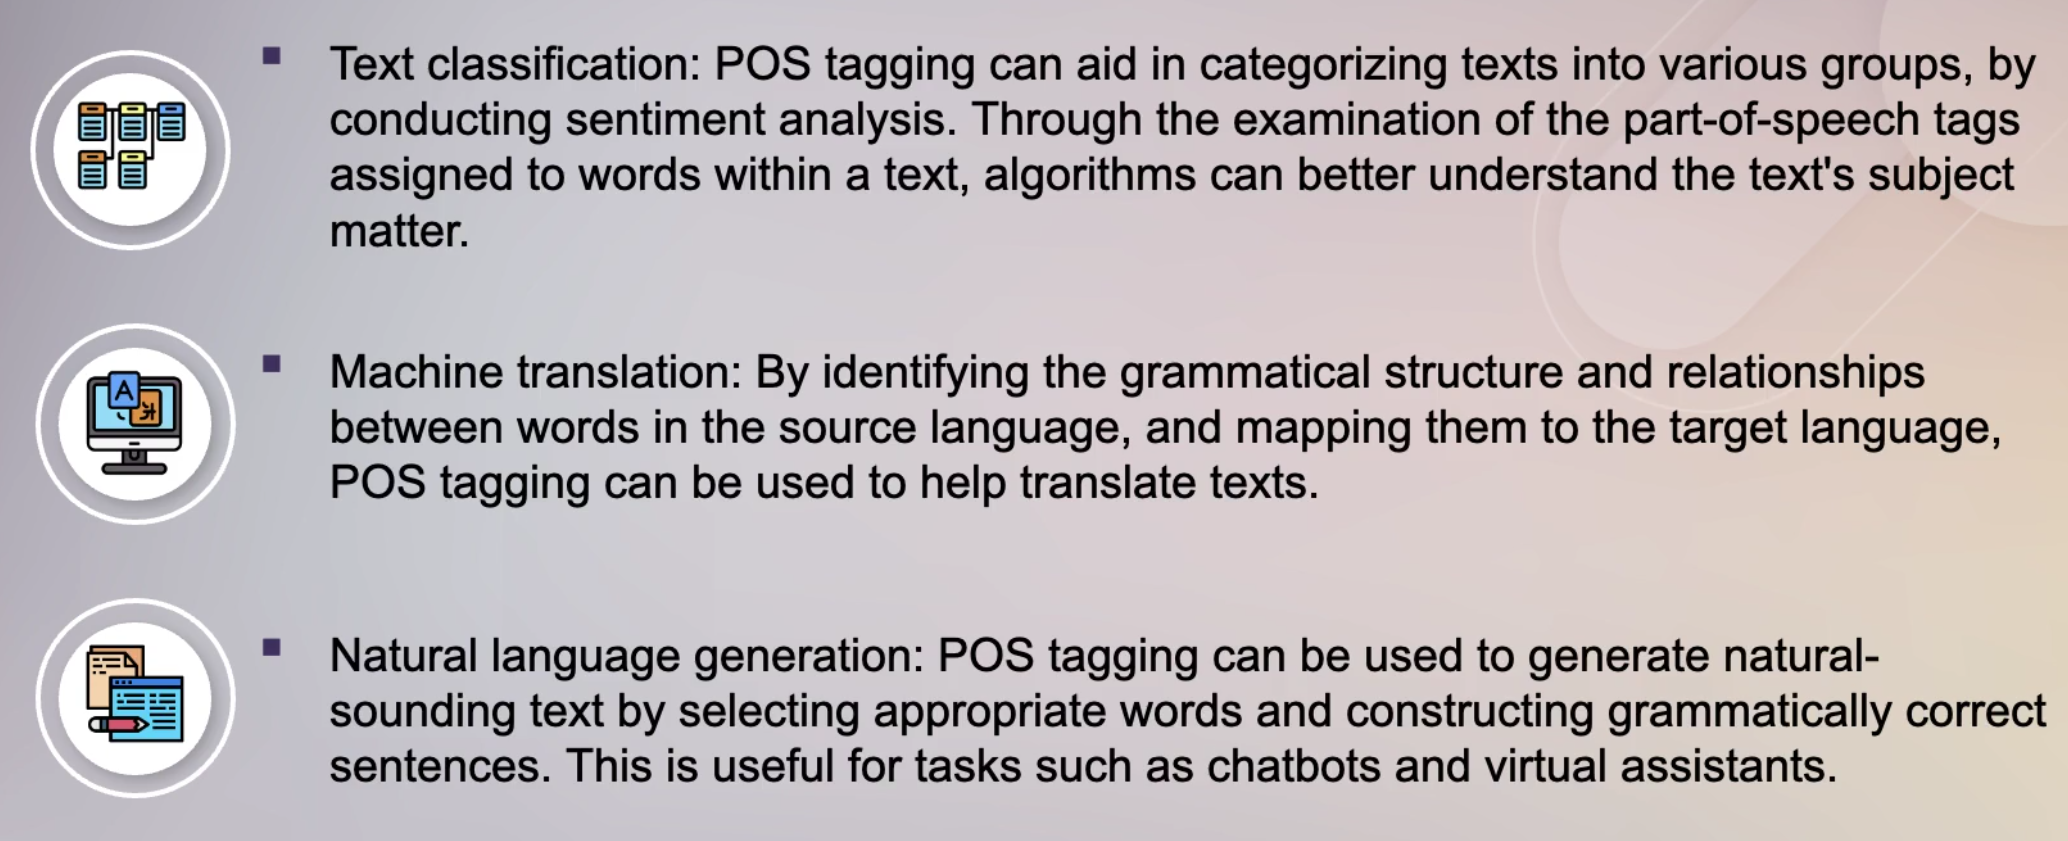
A tag is what Lemmatization needs before it can pick the right dictionary form.