Introduction
The minimum distance classifier assigns to the class with the nearest mean in ordinary Euclidean distance. It comes from special case 2 of the Gaussian Bayes classifier, , when all priors are also equal. Every class cloud is then a circle (a sphere) of the same size, so the ruler distance is the right distance. The note ends with the recipe that turns sample points into any of the Gaussian classifiers.
Main idea
With $\boldsymbol{\Sigma}_i=\sigma^2\mathbf{I}$, $g_i(\mathbf{x})=\boldsymbol{\mu}_i^T\mathbf{x}-\frac{1}{2}\boldsymbol{\mu}_i^T\boldsymbol{\mu}_i+\sigma^2\ln p(\omega_i)$, and the boundary is a hyperplane perpendicular to the line linking the two means. With equal priors, $g_i(\mathbf{x})=-\|\mathbf{x}-\boldsymbol{\mu}_i\|^2$: assign $\mathbf{x}$ to the nearest mean. This is template matching.
Overview
Step 1: special case 2
All classes share the same diagonal, scalar covariance matrix , where is the identity matrix.
When this case happens:
- all features (components of ) are statistically uncorrelated, so every covariance is zero
- every feature has the same variance
- every class cloud is a circle in 2D, or a sphere in higher dimensions, of the same size
Note that:
The determinant is the product of the diagonal entries, each .
Step 2: discriminant function
The covariance is shared, so start from the linear case and put in :
The quadratic term is the same for all classes, so drop it. Then multiply by the positive constant :
where and is the threshold or bias for class . It is a linear function of , so this is still a linear classifier, now with weights equal to the class means.
Step 3: decision boundary
The normal vector of this hyperplane is itself. So the equation defines a hyperplane orthogonal to the line linking the two means.
Where it sits:
- with equal priors it passes through the midpoint , so it is the perpendicular bisector of the two means
- with it moves away from , so the more common class gets a larger region
- the shift is larger when is larger: with wide classes the measurement says less, so the prior matters more
Step 4: equal priors and template matching
Recall the score before expanding:
If the prior probabilities are the same for all classes, can be dropped. Multiply by the positive constant :
is the squared Euclidean distance, and the minus sign makes the largest score the smallest distance. Using the distance instead of its square gives the same decision: distances are never negative and squaring keeps their order, so the nearest mean is the same either way. The optimum decision rule can now be stated very simply:
- measure the Euclidean distance from to each of the mean vectors
- assign to the class of the nearest mean
Such a classifier is called a minimum distance classifier. If each mean vector is thought of as an ideal prototype, or template, for the patterns of its class, this is essentially a template matching procedure.
flowchart TD
    A["Gaussian classes<br/>Σi = σ²I"] --> B{"Equal priors?"}
    B -->|"No"| C["Linear classifier<br/>gi(x) = μiᵀx − μiᵀμi/2 + σ² ln p(ωi)"]
    B -->|"Yes"| D["Minimum distance classifier<br/>gi(x) = −‖x − μi‖²"]
    D --> E["Template matching<br/>nearest mean"]
Why a dot product measures match: is large when points the same way as the template . The same operation appears as the neuron , a convolution filter laid on a window, and the attention score (Dot Product and Projection in Pattern Recognition).
Step 5: from samples to a classifier
In practice the means and covariances are not given, only labelled sample points. This recipe ties all the Gaussian classifiers together:
- estimate and for each class from its samples, as in Gaussian Discriminant Function
- compare the covariance matrices to choose the case
- write with the formula of that case and the given priors
- state the rule: decide the class with the largest
- solve and simplify to get the boundary
- check the answer
flowchart TD
    A["Estimate Σ̂1 and Σ̂2"] --> B{"Σ̂1 = Σ̂2 ?"}
    B -->|"No"| Q["Quadratic classifier<br/>curved boundary"]
    B -->|"Yes"| C{"Σ̂ = σ²I ?<br/>zero covariance,<br/>equal variances"}
    C -->|"No"| L["Linear classifier<br/>tilted hyperplane"]
    C -->|"Yes"| D{"Equal priors?"}
    D -->|"Yes"| M["Minimum distance<br/>perpendicular bisector"]
    D -->|"No"| L2["Linear, Σ = σ²I<br/>perpendicular hyperplane,<br/>shifted by the priors"]
A quick test for step 2: subtract each class mean from its own samples. If two classes give the same list of offsets, they have the same . With real samples the estimates are never exactly equal, so treat nearly equal ones as equal and say so.
Checks for any answer:
- with equal priors and a shared covariance, the boundary passes through the midpoint of the means
- with the boundary is always perpendicular to the line of means, and with any other shared it is usually tilted
- each class mean lands on its own side of the boundary
- with unequal priors, the boundary moves toward the mean of the less common class
- say which side of the boundary is which class
Reading a problem:
- "optimal threshold" or "Bayes classifier" means compare for each class
- PDFs drawn for each class are usually the class-conditional PDFs , so check whether the priors are already multiplied in before using them
- "Gaussian" with sample points means estimate and first
- "equally likely" means equal priors, so the terms cancel
- "find the Bayes classifier" means give the scores and the rule, and "find the decision boundary" means give the equation where the scores tie
Why do we need this
It is the simplest Gaussian classifier and shows the core idea in its plainest form: pick the nearest class centre. It is also a quick check, because a more general classifier must give this same boundary when and the priors are equal.
Next step
All of this assumes each class is a Gaussian with known or estimated parameters. General Statistical Estimation and Machine Learning shows how to estimate from samples, with or without that assumption.
Visual 1: nearest of three templates
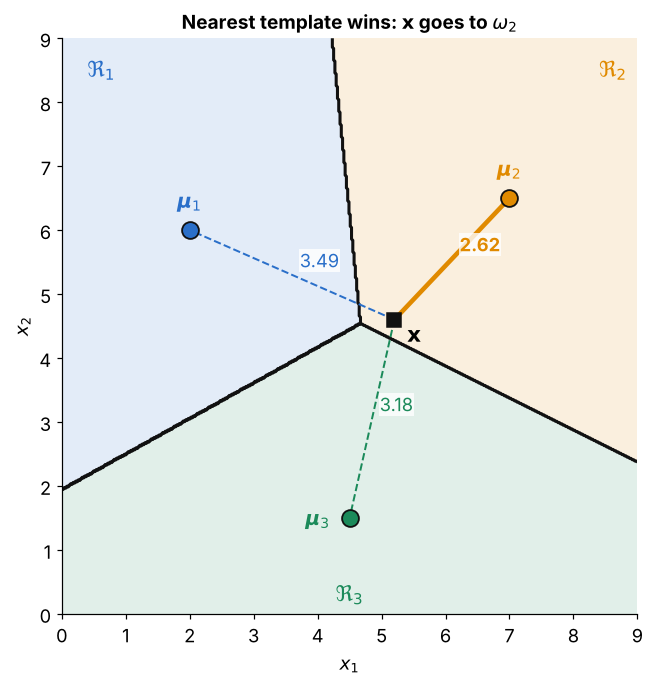
How to read it:
- the dots are three class means used as templates, and each shaded region holds the points nearest to one of them
- the black borders are pieces of the perpendicular bisectors between pairs of means
- for the test point the lengths are , and , so it goes to
- this is the rule of Step 4 with and equal priors
Visual 2: prior shift grows with the spread
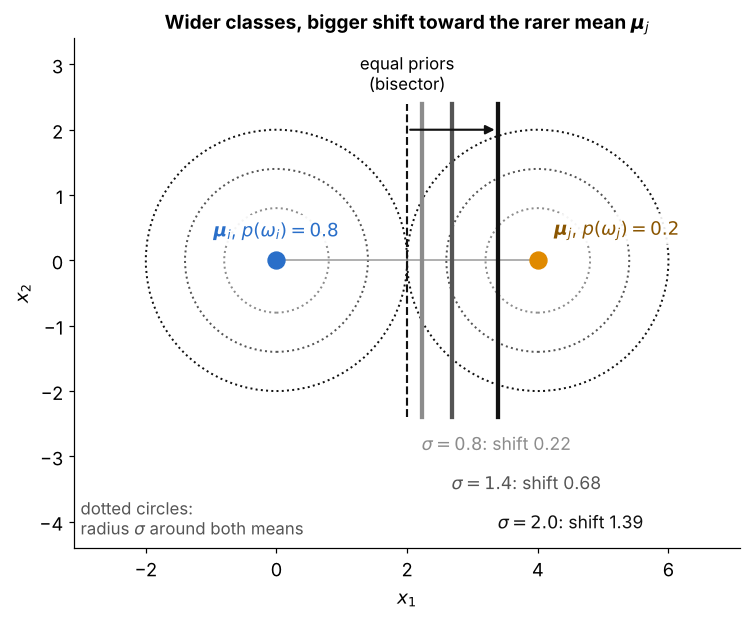
Same means and priors and , three values of :
- with equal priors the boundary would be the dashed bisector
- the unequal priors push it toward the rarer mean by , from the boundary equation of Step 3
- the shift is , and for , and : wide classes make the measurement weak, so the prior matters more
- the dotted circles of radius around both means show the spread, and the boundary stays perpendicular to the line of means in every case