Overview
- AGUVIS is a GUI agent that sees the screen only as an image
- one shared pyautogui action space lets one model work on web, desktop and mobile
- it thinks out loud (inner monologue) before each action
- it is trained in two stages: grounding first, then planning and reasoning
AGUVIS is a pure-vision GUI agent. It sees the screen only as an image and acts through one shared action space, so the same model works on web, desktop and mobile.
Problems it fixes
- different platforms describe the screen in different text formats: HTML for web, the accessibility tree (AXTree) for the OS, and XML for mobile
- weak visual grounding: earlier agents could not locate the right element in the image
- reactive actions with no reasoning: earlier agents acted without explaining why
Solution
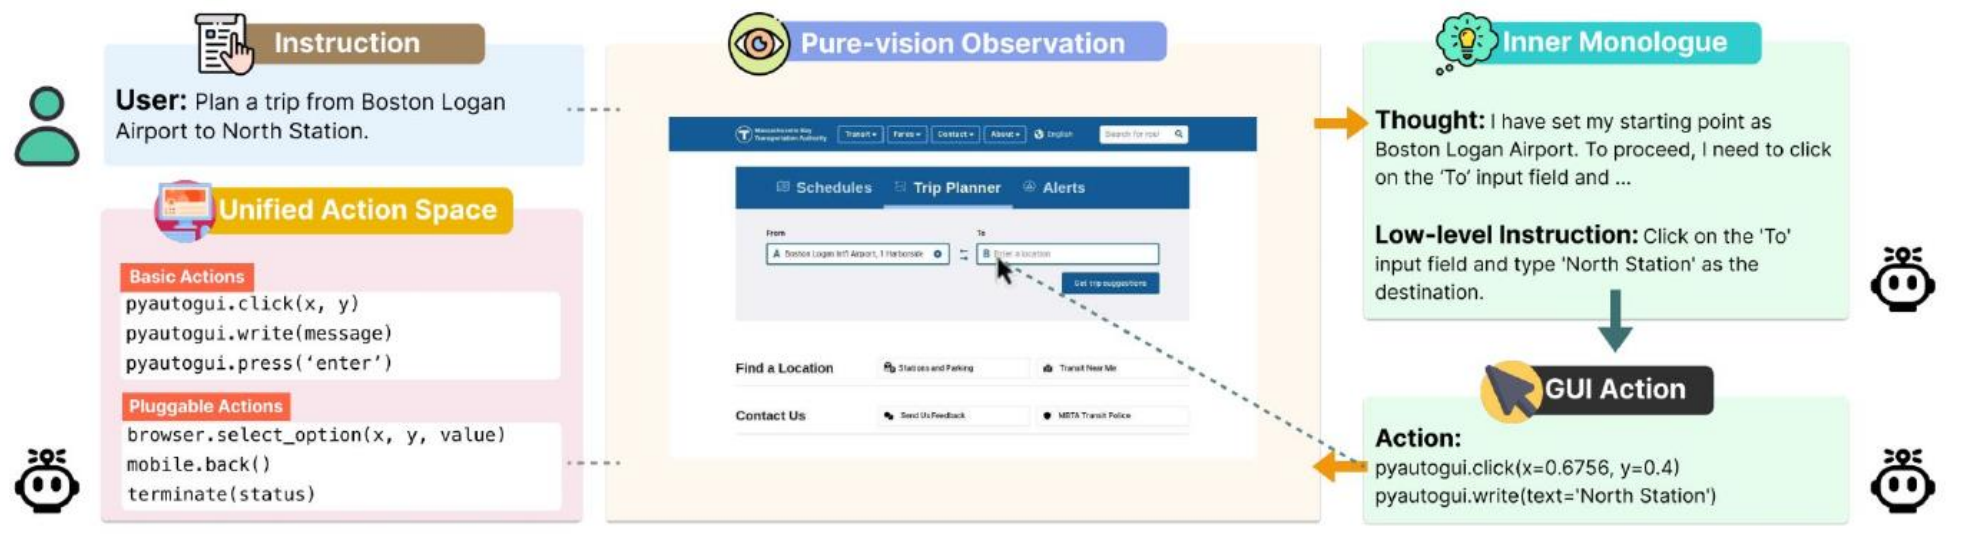
- vision-only observation: the agent sees only the screenshot
- one unified action space in pyautogui, with basic actions (click, write, press) and pluggable actions for special cases (for example browser select_option, mobile back, terminate)
- an inner monologue before each action: a thought ("I have set my starting point as Boston Logan Airport..."), a low-level instruction ("click on the 'To' input field and type 'North Station'"), then the GUI action
- stage 1, grounding: trained on more than 1M samples that link instructions to screen locations
- stage 2, planning and reasoning: trained on 35K trajectories that include the inner monologue
Note
AGUVIS is a model and system pillar of a multimodal agent.