Motivation
We need to understand or measure the difference between the true probability distribution and our observed probability distribution.
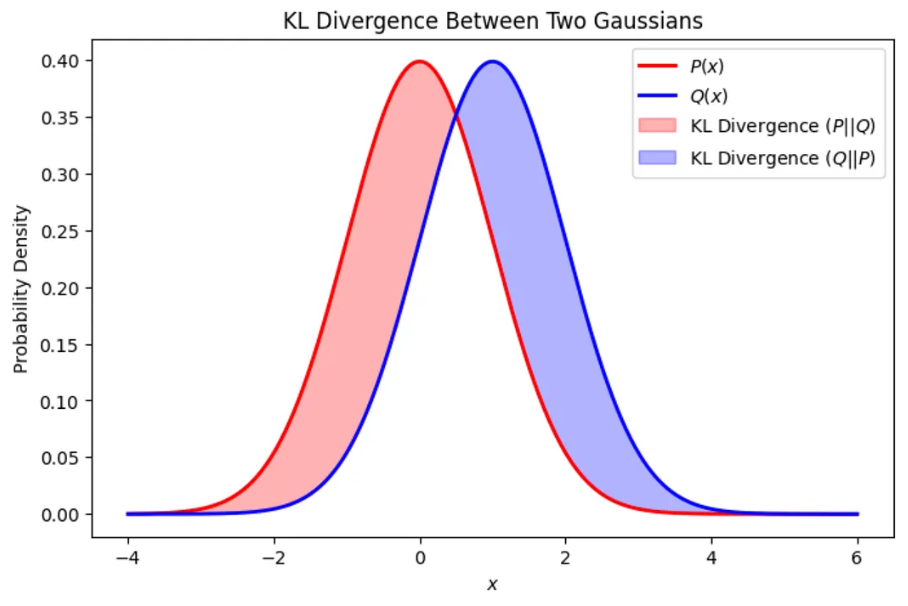
KL Divergence is a type of statistical distance between 2 probability distributions which is our true distribution, vs the probability distribution which is the approximating model distribution. KL divergence is also known as the information gain or relative entropy.
KL Equation for Guassian
- this equation is used for squashing vector embeddings in the latent space into having a of 0 and of 1
- this is for the Variational Autoencoder (VAE)